Selecting and orchestrating cloud storage is no longer a simple matter of choosing an offsite digital filing cabinet. In an era dominated by distributed workforces, petabyte-scale data ingestion, and rigorous compliance mandates, unstructured data storage defines an organization’s operational agility and cost structure. Whether supporting distributed teams, training proprietary machine learning pipelines, or safeguarding mission-critical disaster recovery targets, your data retention architecture directly determines enterprise resilience.
Treating storage merely as an outsourced commodity exposes organizations to vendor lock-in, ballooning egress penalties, and unmonitored security misconfigurations. A robust cloud storage strategy requires a deep technical understanding of object storage tiers, envelope encryption, life-cycle policies, and regulatory compliance frameworks. By deploying deterministic data lifecycle rules and zero-knowledge encryption mechanisms, modern operations can achieve maximum data availability while strictly controlling recurring operational expenditures.
Key Takeaways
- Storage Tiers Dictate Economics: Aligning data access frequency with specialized storage classes (Hot, Warm, Cold, and Deep Archive) prevents excessive operational expenses and automates tier progression.
- Client-Side, Zero-Knowledge Encryption is Mandatory: Storing encryption keys client-side ensures that even in the event of a provider-level breach or sub-processor compromise, raw data remains mathematically illegible.
- Beware of Egress and API Call Premiums: Data ingestion is almost universally free, but extracting petabyte-scale datasets or executing high-frequency
GET/PUTrequests across vendor boundaries carries substantial hidden fees. - The 3-2-1-1-0 Backup Rule Defines Real Durability: Combine public cloud buckets with an immutable, air-gapped target to eliminate single points of failure, ransomware encryption, and accidental deletion.
Technical Comparison: Core Cloud Storage Paradigms
Optimizing digital assets requires matching data types to their ideal underlying storage architecture.
| Storage Architecture | Primary Data Structure | Common Protocols / APIs | Optimal Use Cases | Latency & Performance Profile |
| Object Storage | Unstructured blobs with custom metadata and unique IDs | RESTful HTTP/S, Amazon S3 API, Azure Blob | Media archives, backup repositories, AI datasets, data lakes | High throughput, higher time-to-first-byte ($TTFB$) |
| Block Storage | Fixed-size raw blocks without metadata (resembles a physical drive) | iSCSI, Fibre Channel, NVMe-oF, Cloud EBS | Virtual machine system disks, transactional relational databases ($RDBMS$) | Ultra-low latency, high random $IOPS$ |
| File Storage | Hierarchical directory and folder file tree | Network File System ($NFS$), Server Message Block | Centralized collaboration drives, legacy enterprise migration, shared home directories | Balanced throughput and moderate latency |
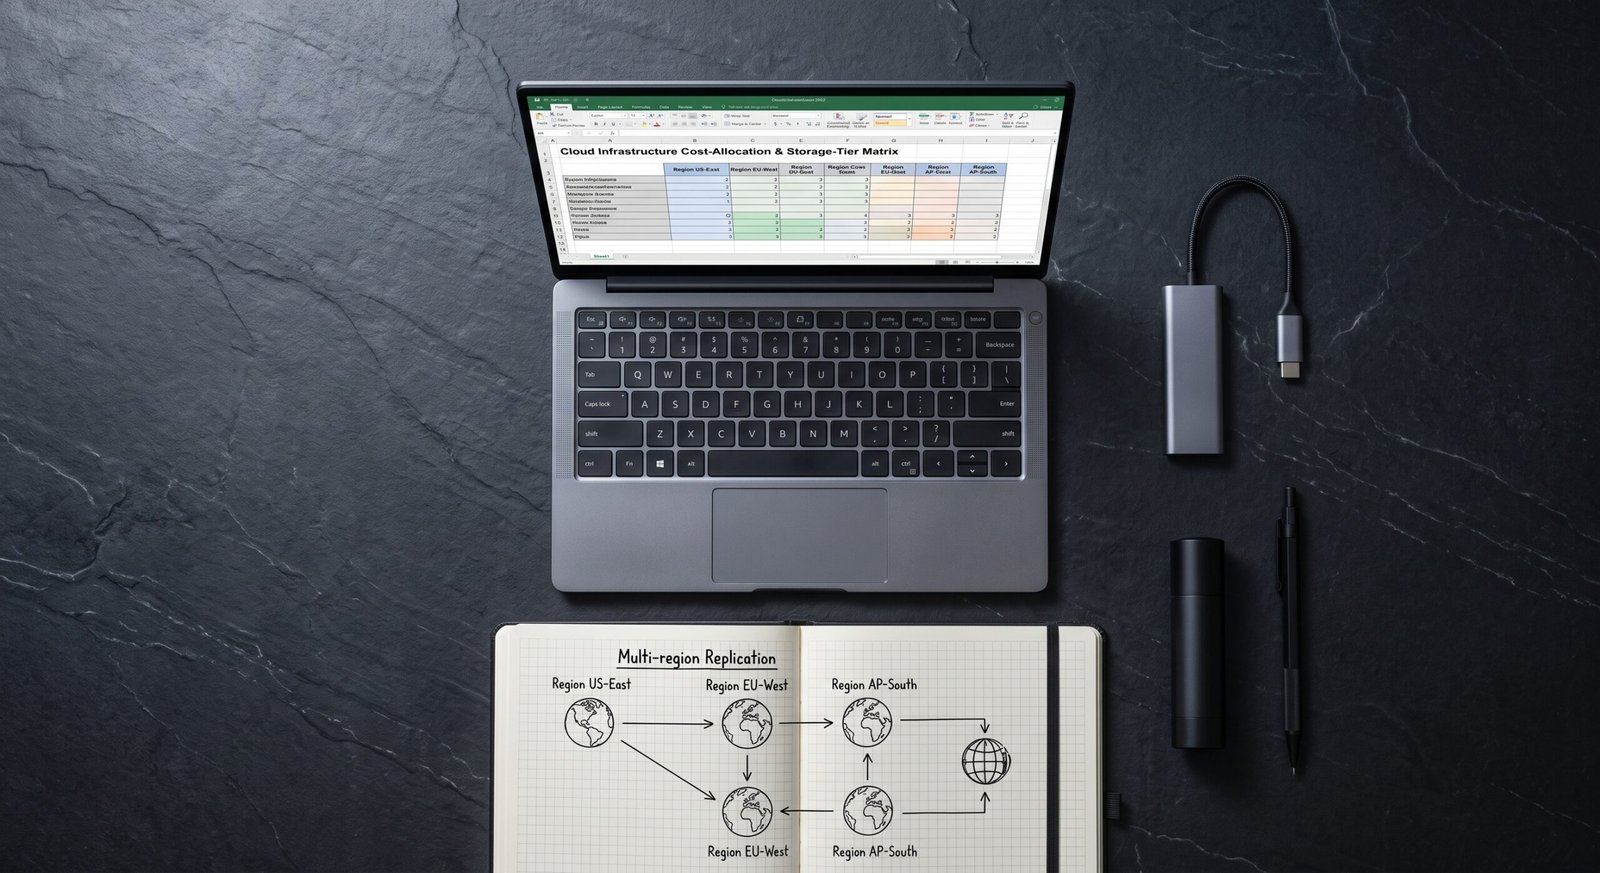
3 Foundational Pillars of Modern Cloud Storage Management
Deploying a sustainable storage repository requires moving past standard desktop synchronization tools toward deterministic, policy-driven infrastructure.
1. Object Lifecycle Policies and Tiering Automation
Unmanaged repositories naturally accumulate stale datasets, resulting in unnecessary expenditures for high-availability hot storage.
- Automated Expiration and Transition Rules: Establish deterministic lifecycle rules that automatically transition data from standard “Hot” tiers to “Cool” tiers after 30 days of inactivity, followed by migration to “Archive” or “Glacier” tiers at 90 days.
- Multi-Part Upload Optimization: For massive media assets and database snapshots, split files into distinct chunks to allow parallel upload streams and resume broken transfers without restarting from scratch.
2. Zero-Knowledge Cryptography and Identity-Bound Access
Default server-side encryption provided by hyperscalers protects data on physical drives, but leaves access vulnerable to compromised administrative credentials.
- Bring Your Own Key & Envelope Encryption: Maintain key generation and rotation authority inside a dedicated Hardware Security Module .The storage provider should only process encrypted blobs without having access to master decryption keys.
- Principle of Least Privilege for S3 Buckets: Disable all public read/write permissions by default. Restrict bucket access strictly through granular IAM roles, IP whitelisting, and conditional multi-factor authentication triggers.
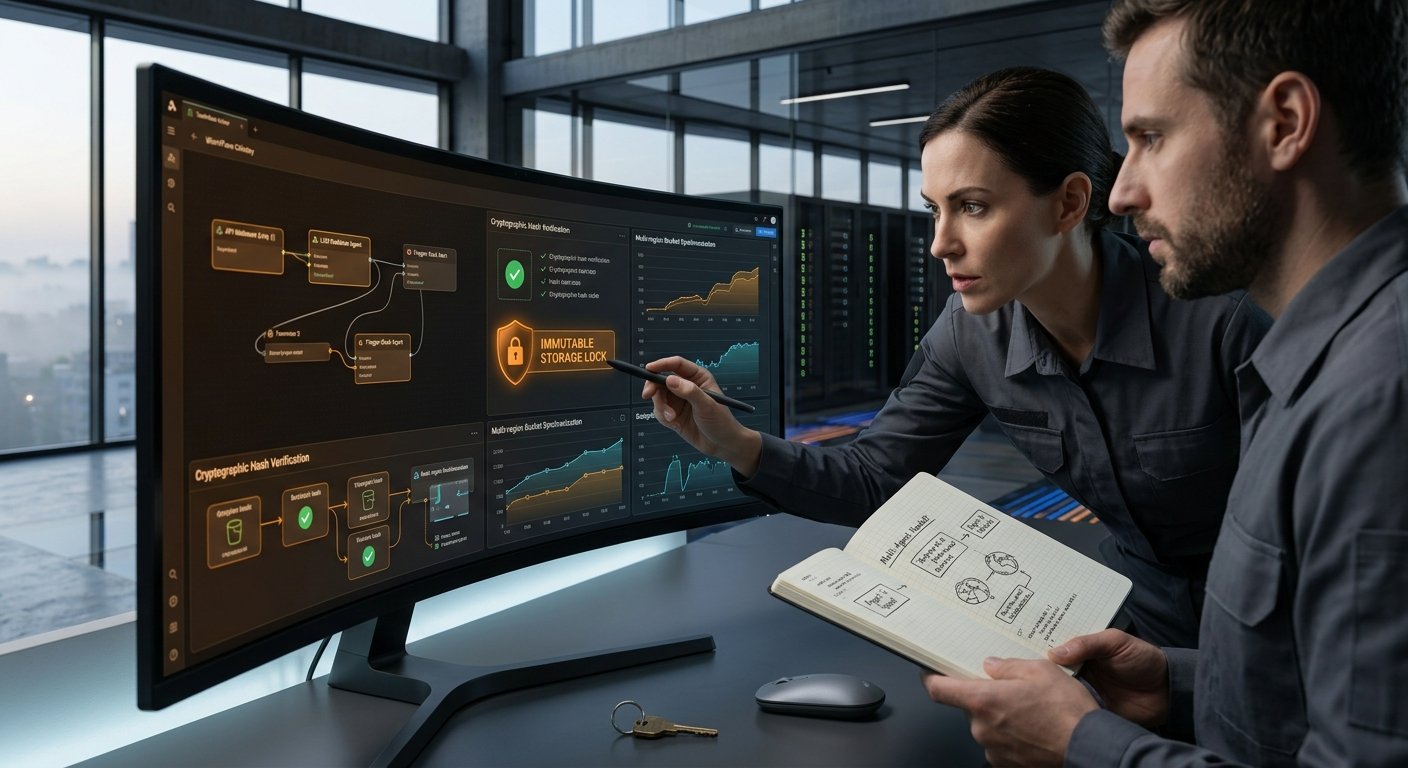
Mitigating Ransomware and Silent Bit Rot
Long-term file preservation requires proactive defenses against malicious tampering and physical media degradation:
- Object Versioning and Immutable Storage Locks: Enable Object Lock in “Compliance Mode” with Write Once, Read Many ($WORM$) policies. Even if root administrator credentials are breached, malicious actors cannot delete, overwrite, or encrypt protected objects until the retention period expires.
- Continuous Checksum Validation: Deploy automated integrity hashing (
SHA-256orMD5) during data transfer and at rest. Automated background scans detect silent bit degradation or incomplete packet transfers before corrupt files overwrite functional backups. - Egress Cost Mitigation via Edge Caching: Mitigate unpredictable network egress fees by implementing content delivery networks (CDNs) or Cloudflare-style zero-egress storage bridges for frequently requested public assets.
Long-Term Data Sovereignty and Operational Freedom
A modern cloud storage framework balances instant accessibility with absolute data ownership. By structuring automated lifecycle transitions, enforcing client-side cryptographic isolation, and locking down egress vulnerabilities, you prevent platform dependency while preserving operational flexibility. Treating your storage architecture as a strategic foundation ensures that critical enterprise data remains durable, cost-effective, and fully protected against shifting digital threats.
Frequently Asked Questions About Cloud Storage
What is the difference between Hot, Cold, and Archive cloud storage tiers?
Hot storage is engineered for frequently accessed, mission-critical data, offering the lowest access latency and cheapest read/write request fees, but the highest monthly storage cost per gigabyte. Cold and Archive tiers (such as AWS Glacier or Azure Archive) offer ultra-low per-gigabyte hosting rates, making them ideal for compliance records and long-term disaster backups; however, they require retrieval windows ranging from minutes to hours and assess retrieval fees when reading data.
How does zero-knowledge encryption protect cloud-hosted files?
In standard cloud setups, the provider manages the encryption keys, meaning the host can decrypt files if legally compelled or if internal administrative accounts are compromised. Zero-knowledge encryption ensures that files are encrypted locally on the user’s or enterprise’s machine before transmission, using private keys that never leave the local environment. The cloud host stores only unreadable ciphertext and cannot access the underlying data.
Why do organizations incur high cloud storage bills despite low advertised per-gigabyte costs?
Advertised pricing typically highlights raw storage costs (e.g., pennies per gigabyte per month), but omits auxiliary transactional fees. Real-world bills often surge due to data egress fees (charges for downloading or migrating data out of the provider’s network), high-volume API requests (LIST, GET, PUT), and inter-region data replication charges that compound rapidly as workloads scale.
1 thought on “Cloud Storage: Strategy for Zero Knowledge Security”